
Detectors expose AI-generated text by targeting the predictable structure of machine reasoning
New detection systems expose machine-generated text by targeting the uniform logic that separates AI from messy, chaotic human thought.
June 24, 2026
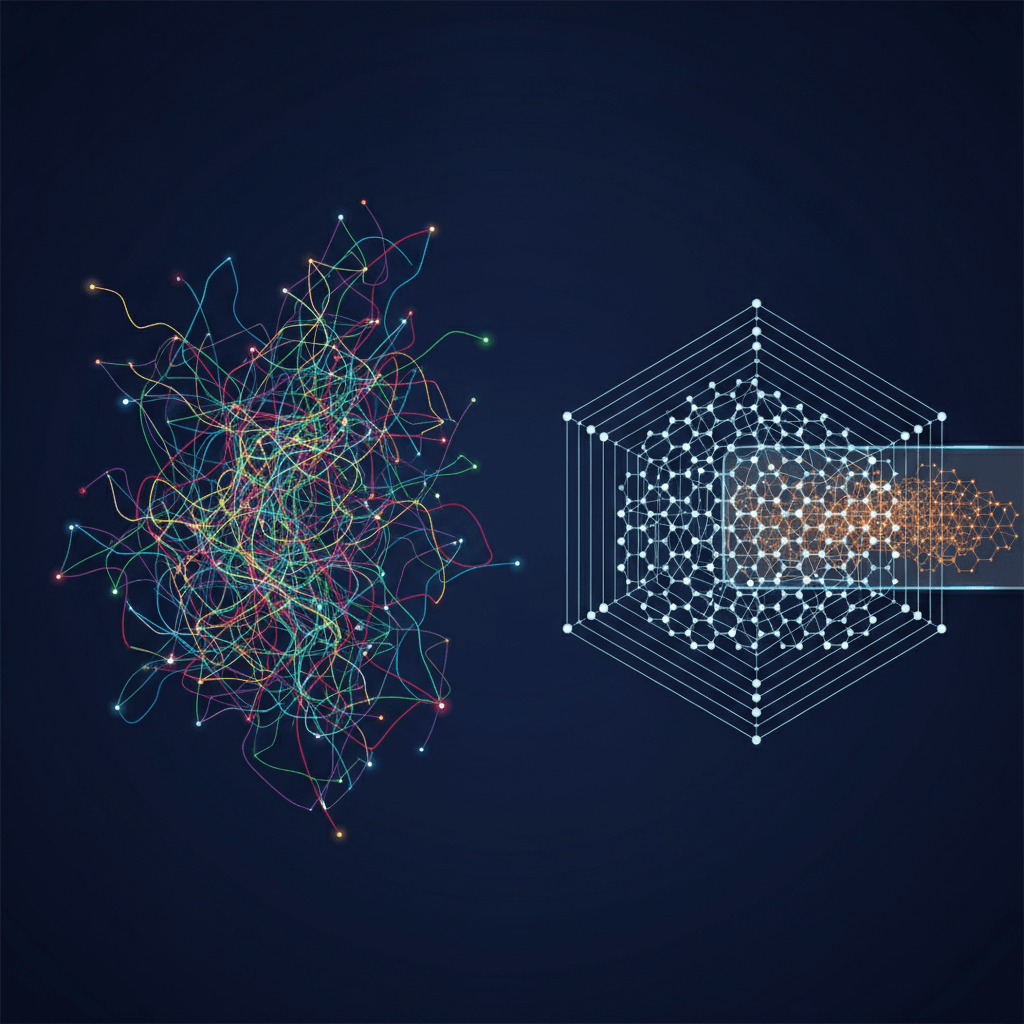
The rapid ascent of generative artificial intelligence has fundamentally disrupted the landscape of written communication, raising a crucial question for educators, publishers, and everyday readers: how can we reliably distinguish human writing from machine-generated prose? While modern large language models can produce grammatically flawless, persuasive, and highly informative copy that easily outmatches the writing abilities of the average person, they possess a structural Achilles' heel that gives them away[1]. According to Max Spero, the co-founder and chief executive officer of the AI-detection company Pangram Labs, the definitive giveaway is not a specific word choice or grammatical quirk, but rather a lack of intellectual diversity[2][3]. In a recent interview published on the platform AI Policy Perspectives and highlighted by the technology outlet The Decoder, Spero explained that while language models can write exceptionally clean text, they are fundamentally incapable of replicating the messy, sprawling, and diverse nature of human reasoning[3][4]. When pushed to generate numerous arguments on a single topic, the logical pathways of even the most advanced artificial intelligence inevitably cluster within a highly predictable, narrow conceptual band[3][5].
At the core of this detection breakthrough is the inherent uniformity of machine-generated reasoning, a characteristic that contrasts sharply with the chaotic nature of human thought. Spero notes that if a user asks a high-performing large language model to produce 100 arguments on a complex issue, those arguments will almost always cluster tightly together, sharing a highly centralized logical foundation[3][5]. This clustering occurs because language models are fundamentally probabilistic machines designed to compute and deliver the most mathematically plausible sequences of words and concepts based on their training data. Humans, by contrast, do not think or argue in standardized mathematical curves. Human reasoning is a tapestry woven from idiosyncratic lived experiences, varied cultural contexts, emotional biases, and creative leaps of faith. Consequently, if 100 different humans are asked to argue a point, their reasoning will scatter wildly across a vast, unpredictable spectrum. This stark difference in cognitive distribution means that even if a machine writes cleaner sentences than a human, the underlying structure of its arguments will remain uniform, leaving a distinct pattern that sophisticated detection models can spot[3][6].
This structural predictability leads to a counterintuitive paradox in modern artificial intelligence development: as frontier models become more capable, they actually become easier to detect[7][8]. Spero pointed out that older, less advanced models, such as GPT-2 and GPT-3, were significantly more difficult for detection algorithms to identify[8]. These early systems were trained primarily to mimic the raw, unaligned distribution of human writing scraped from the internet, which meant they inherited much of humanity's erratic stylistic variance[8]. However, to make newer frontier models highly useful, safe, and commercializable, AI developers must employ techniques like Reinforcement Learning from Human Feedback to instill strong, explicit preferences[8]. These systems are trained to "prefer" highly structured, polite, and optimized formats, steering them away from controversial or incoherent phrasing[8]. Ironically, it is precisely these instilled preferences that act as a beacon for detectors like Pangram[8]. By forcing an artificial intelligence to consistently choose the most polished and aligned path, developers inadvertently narrow the model's stylistic and logical variance, creating a rigid behavioral profile that stands out to deep-learning classifiers[8].
To capture these highly nuanced structural patterns, modern detection technology must move beyond simple, surface-level markers[9][10]. Spero openly describes Pangram's deep-learning classifier as a "black box," acknowledging that the company does not have absolute interpretability into every micro-prediction the algorithm makes[11][10]. While the tool highlights specific suspicious phrases to help users train their own eyes, its neural network is actually analyzing longer-context features and identifying the subtle, systemic patterns that a language model leaves behind when organizing a document[12][10]. To keep up with the continuous advancements of major AI developers, Pangram trains its classifier using "synthetic mirrors" of the most difficult-to-classify documents, iteratively retraining the system to minimize false positives[9]. This methodology allows the classifier to maintain high accuracy even when facing "humanizers"—automated paraphrasing programs designed specifically to bypass AI detectors by swapping out common vocabulary[9]. Because Pangram's software looks at the broader architecture of how arguments are constructed and organized rather than just individual words, surface-level editing tools are increasingly ineffective at masking machine authorship[9].
The rise of undetectable machine writing and the subsequent development of advanced filters carry massive implications for the future of digital society[13][4]. Spero frames this challenge around a fundamental "social contract" that has historically governed human communication: an author pays an intellectual cost to write and formulate an idea, and a reader pays a cost in time to consume and evaluate that idea[4]. When generative artificial intelligence is used to bypass the author's cost, the internet is rapidly flooded with "AI slop"—low-effort, automated content that requires zero human labor to produce but still demands valuable human attention to read[13][4]. Spero warns that if left unchecked, up to 80 to 90 percent of the internet could become machine-generated within a few years, effectively rendering traditional search engines, social media networks, and online discourse useless[14]. By implementing robust detection systems, platforms and readers can establish content filters akin to traditional email spam filters, preserving spaces for authentic human exchange[14]. Spero argues that detection is not about moral policing, but rather about empowering readers with the transparency needed to decide what kind of content they want to spend their cognitive energy on[14].
Ultimately, the evolution of generative artificial intelligence has moved the battleground of digital authenticity from superficial stylistic markers to the very structure of thought[15][10]. As language models continue to refine their prose, attempting to catch them through grammar, spelling, or vocabulary will become an exercise in futility[15]. Instead, the ultimate tell of machine-generated content remains the rigid, clustered nature of its reasoning, a byproduct of the mathematical constraints and behavioral alignment embedded by its creators[3][8]. So long as humans maintain their messy, unpredictable, and diverse ways of looking at the world, human thought will retain a unique signature that cannot be replicated by algorithms. In a world increasingly saturated by synthetic information, advanced detection tools that analyze the architecture of argument are becoming vital infrastructure, serving to preserve the integrity of the written word and protect the shared spaces of human intellect[13].